Connect
November 23–27, 2026
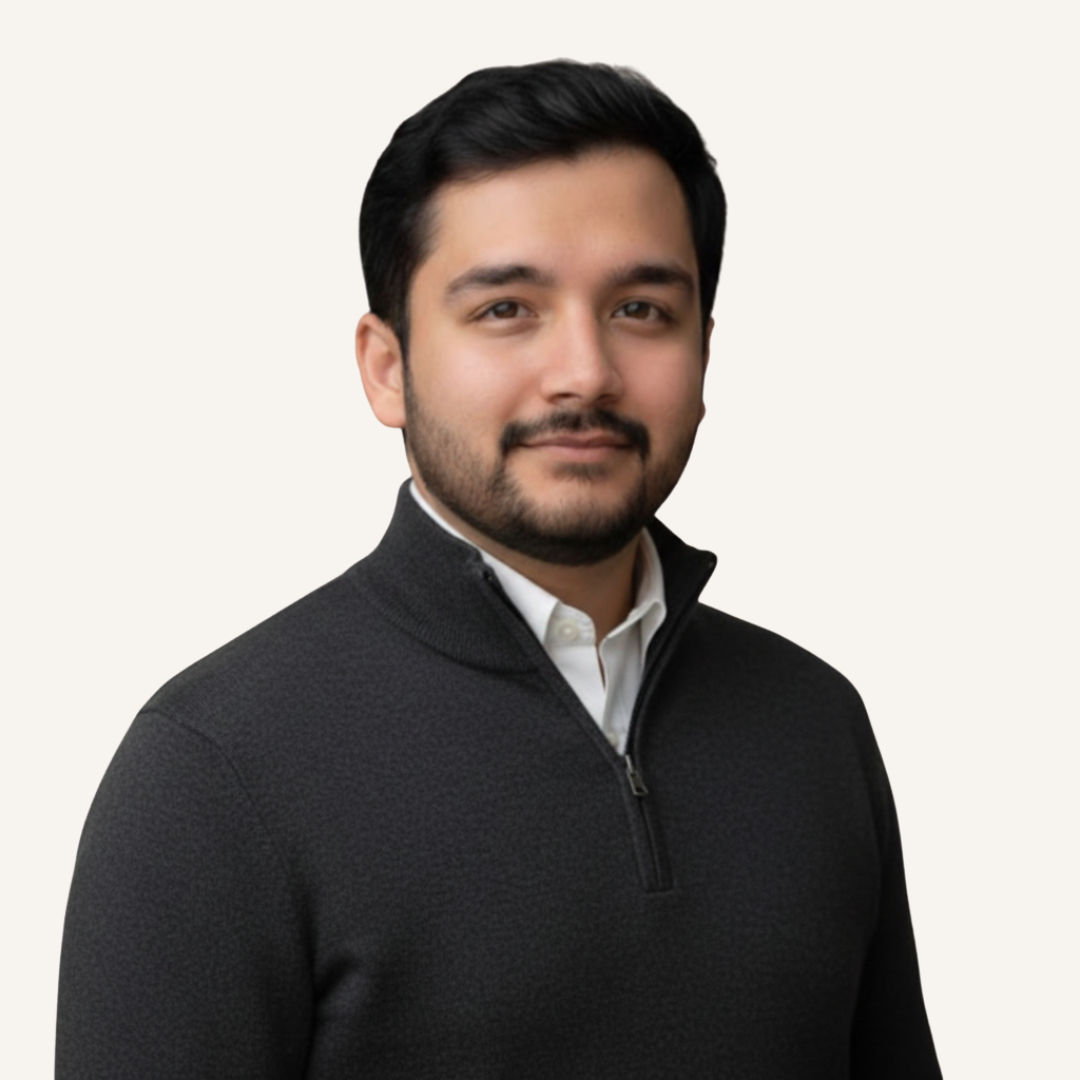
Danish Azhar
Associate, DashMart - Supply Chain ProdOps
DoorDash
Session Details
The Feedback Trap: Why Autonomous AI Agents Learn to Repeat Their Own Mistakes
Agentic AI is graduating from advice-giver to actor. Across the industry, agents are moving from "here's what I'd suggest" to writing directly into production systems: placing purchase orders, adjusting prices, throttling supply, approving credit. The moment an agent starts doing that, it closes its own feedback loop, observing the outcome of a decision it made itself and using that outcome as its next training signal. Most of today's agentic AI conversation is about how to get agents to act autonomously. This talk is about what happens after they do. Two well-documented statistical failure modes, endogeneity and outcome censoring, guarantee that an agent given full, closed-loop autonomy over a real operational process will start to systematically mislead itself, and will do so faster than a human-supervised process ever would, precisely because no one is left in the loop to notice. Give an agent control over inventory, and its own past decisions to under-stock an item corrupt the very data it later uses to decide how much to stock. The agent doesn't just make a mistake: it learns to trust the mistake, and the faster its decide-act-observe loop runs, the faster that trust compounds. I lead the analytics function behind exactly this kind of system: an autonomous supply and inventory decision engine running across a network of on-demand retail fulfillment centers at DoorDash. I've also published two peer-reviewed frameworks, in International Journal of Production Economics and Transportation Research Part E (both Q1 journals), for detecting and correcting these exact biases in operational AI/ML models. This talk translates that research into the language of agent design for the first time: not "how do we build smarter agents," but "how do we build agents that don't get systematically worse the longer we let them run." Attendees will leave with a working understanding of why full autonomy, not partial or human-checked autonomy, is what triggers this failure mode, and why faster agent decision loops make it worse rather than just different. They'll get a three-question diagnostic they can run today to check whether their own production agent is already caught in this trap, along with a lightweight architecture pattern, built on exploration budgets, counterfactual logging, and periodic causal audits, for designing agents that self-correct instead of self-reinforce. The talk closes with a real, production-scale account of applying this inside a physical retail supply chain: what failed, how it was caught, and what changed once the fix was in place. This isn't a vendor demo or a capability showcase. It's the intersection of two credentials that rarely appear in the same speaker: peer-reviewed, published causal-inference research and hands-on ownership of a live, revenue-scale autonomous decision system. Most agentic AI talks focus on what agents can now do; this one focuses on a structural risk that only shows up after that capability arrives, backed by original published methodology rather than anecdote, giving engineers and product leaders building agentic systems today a way to see a failure mode before it costs them, not after.
Full conference agenda
See every session across the AI Agents Conference November 2026 line-up.
View Agenda