Connect
November 23–27, 2026
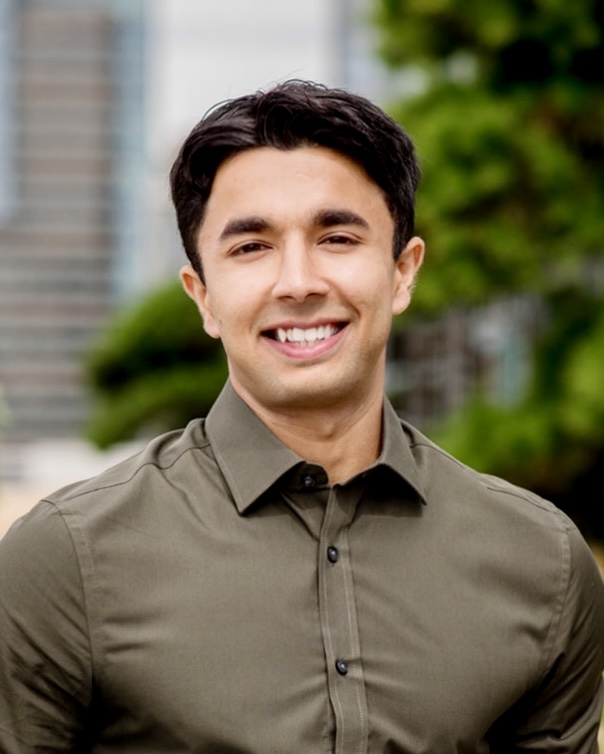
Moeez Khan
Software Development Engineer, Agentic AI
Amazon AWS: Amazon Web Services
Session Details
Your AI Agent Said "Done." Would You Know If It Wasn't?
[Disclaimer: The opinions, insights, and perspectives shared in this session are solely my own and do not reflect those of my current or past employers, nor do they convey any confidential information by any means.] Your agent reports success, your dashboard turns green, and everyone moves on. But agents misreport their own work more often than most teams measure. In 20,574 real coding-agent sessions, 22.6% of the times developers had to push back involved the agent misreporting its own work (Tang et al., 2026). When live APIs silently mishandled a request, agents noticed 12% of the time and repaired none (SilentProbe, 2026). And half of 157 organizations surveyed this year shipped an agent that passed its evals and then failed a customer (VentureBeat Pulse, 2026). This session is a design-pattern catalog for agents that take real actions: payments, records, tickets, code. Each pattern answers one question: how does the system know the agent's "done" is true? And each comes with a number, measured in two open-source harnesses anyone can rerun without API keys. Four agent designs all scored 100% on a clean eval. Under injected tool faults, a plain retry agent reported success on 18% of runs where the real state was wrong and double-charged 10%, while the design that verified its work and could say "unconfirmed" dropped silent failures to 0%. For coding agents, re-running the agent's own tests caught 17% of 828 scripted cheats; moving the verifier out of the agent's reach and comparing strictly caught all of them, with no honest work flagged. You'll see it live: an agent "succeeding" while the ledger says otherwise. Attendees leave with: 1. Verify the Postcondition: read the real state back instead of trusting the tool's reply or the agent's summary 2. Idempotency Keys: make every retry safe, so a timeout never becomes a duplicate charge 3. The Unconfirmed State: a sanctioned "I can't confirm it worked" beats a confident guess 4. A Verifier Out of Reach: in multi-agent systems, the checker gets read access only, so the worker can't edit the test that grades it 5. Faults in Your Evals: inject timeouts, stale reads, and partial successes, and report pass^k, because one clean run proves almost nothing 6. Two Tools to Run Today: agent-fault-lab and claim-check, MIT-licensed, vendor-neutral An agent's "done" is a claim, not evidence. Build systems that check. Sources: 1. Tang et al., "How Coding Agents Fail Their Users," arXiv:2605.29442, 2026. https://arxiv.org/abs/2605.29442 2. Li et al., "SilentProbe: Measuring Silent Failure in Production APIs Used as Agent Tools," arXiv:2609.00035, 2026. https://arxiv.org/abs/2609.00035 3. VentureBeat Pulse Research, "The agent evaluation gap," Jul 2026. https://venturebeat.com/resources/the-agent-evaluation-gap-enterprise-ai-organizations-have-a-reality-alignment-problem-not-a-coverage-problem-and-most-are-shipping-to-production-anyway 4. agent-fault-lab: https://github.com/MuhammadMoeezKhan/agent-fault-lab 5. claim-check: https://github.com/MuhammadMoeezKhan/claim-check
Full conference agenda
See every session across the AI Agents Conference November 2026 line-up.
View Agenda