Connect
November 23–27, 2026
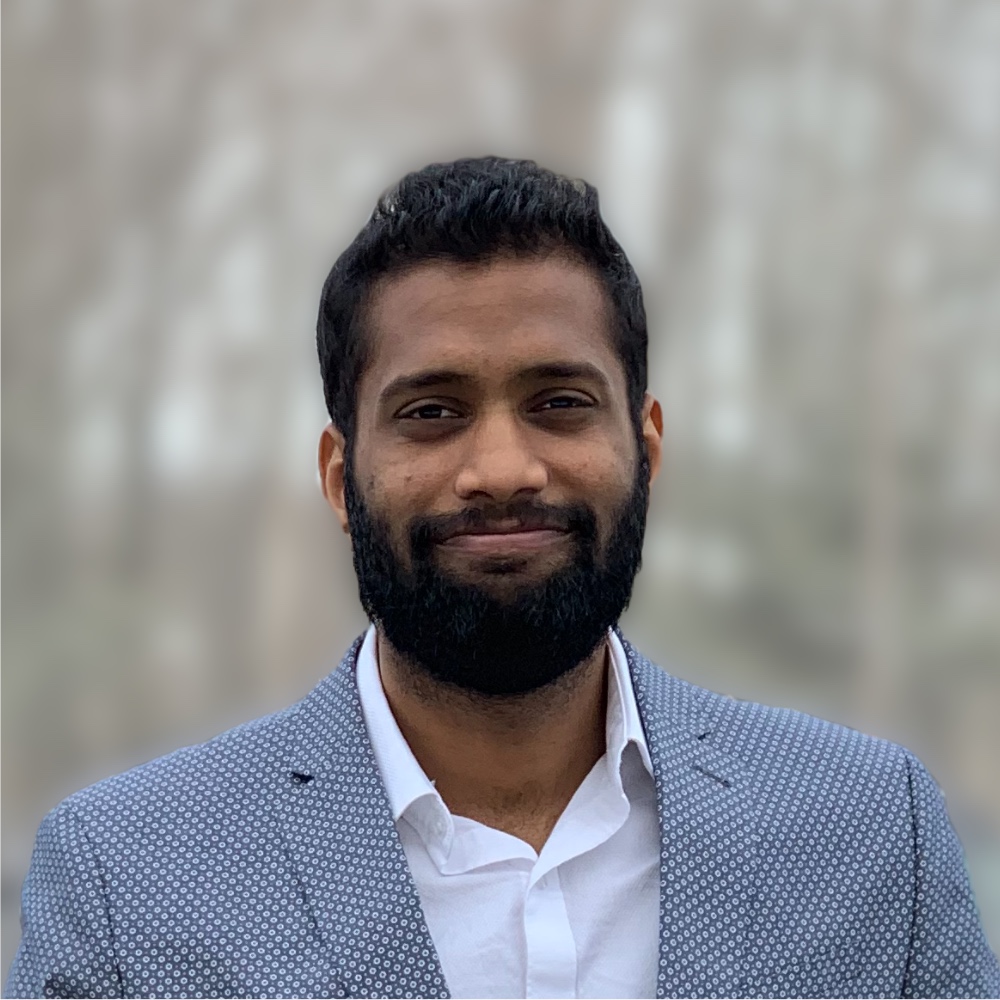
Vamshidher Reddy Jannapu Reddy
Open-source maintainer, AI coding-agent infrastructure and security
Independent researcher
Session Details
Provenance Is Not Authority: Measuring How Much Poisoned Policy an AI-Agent Guardrail Acts On
Guardrails for AI agents are evaluated on whether they block the actions their rules name. That measures the rules, not the guardrail, and it assumes the rules can be trusted. In practice an agent's operational rules come from postmortems, runbooks, tickets and chat, which are exactly the places an attacker, or a confused teammate, can write to. Nobody checks. This session presents a benchmark that asks the missing question: when a rule has been tampered with or forged, how much of it does the guardrail act on? I will walk through the corpus (500 Kubernetes and Terraform constraints seeded from public postmortems and the OPA Gatekeeper library, each labelled Trusted, Untrusted or Malicious, with the labels withheld from the system under test), the metric (poison susceptibility), and the results across a trust-all reference, OPA/Rego, and LLM self-checks with and without an authority map: every verifier without a trust model acted on 100% of poisoned rules; an LLM given the authority map still acted on 52%, exactly the share carried by tampered or forged constraints; checking both the rule's provenance hash and the asserting principal's authority brought it to zero. Then the practical part: an open-source verifier that binds every rule to a source hash and a principal and checks both at decision time, shown as a Claude Code hook, compiled to AWS Service Control Policies, and compiled to a Kubernetes ValidatingAdmissionPolicy, each live-tested. Everything shown is open source (PyPI, GitHub, Zenodo), so attendees can score their own agent guardrails against the same corpus.
Full conference agenda
See every session across the AI Agents Conference November 2026 line-up.
View Agenda